Real-Time Data Pipeline
Problem:
Analytics queries took minutes to return, blocking decision-making.
Solution:
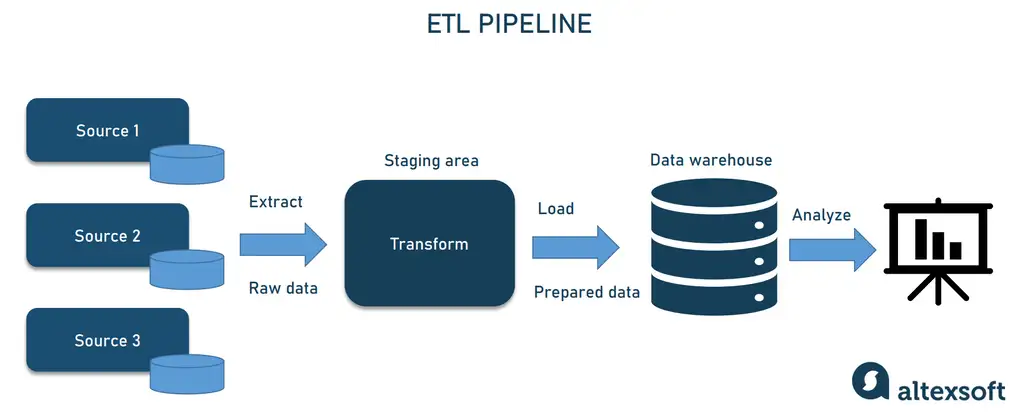
Architected a real-time ELT pipeline using Dagster, DLT, and ClickHouse.
Impact:
Query latency reduced from 5–10 minutes to under 100ms, enabling real-time dashboards.
Overview
From batch pain to near-real-time analytics by orchestrating assets in Dagster and serving ClickHouse for interactive use.
Results & metrics
- Sub-100ms dashboard query latency on ClickHouse compared to 5-10 minute PostgreSQL queries
- Automated incremental CDC extracts every 6 hours with zero operational downtime
- Centralized multi-source analytics uniting MySQL and MongoDB into standardized dbt models
- End-to-end orchestration and alerting with Dagster Cloud and GitHub Actions
Before / after
Query Execution Time
Before: 5 to 10 minutes on production PostgreSQL
Data Ingestion Workflow
Before: Fragile manual cron scripts with untracked failures
Source Unification
Before: Disjointed MySQL and MongoDB data requiring manual spreadsheets
What I built
ELT run by Dagster
Dagster Cloud runs Sling and DLT into ClickHouse, then dbt builds the views.
Sub-100ms dashboards
On ClickHouse, dashboard queries dropped from 5–10 minutes to under 100ms.
Stack
- ClickHouse Cloud, Columnar Store
- Dagster Cloud, Orchestration
- dbt Core, Data Transformation
- Sling & DLT, CDC & Batch Extract
- Metabase, Analytics & BI
Decisions
Key trade-offs and design calls that shaped the final delivery.
Sling for MySQL, DLT for MongoDB
Why
- Context
- Different data patterns—MySQL needed incremental sync, MongoDB full replace
- Decision
- Best-of-breed tools per source rather than one-size-fits-all: Sling for incremental MySQL, DLT for MongoDB collections
Dagster over Airflow
Why
- Context
- Needed modern orchestration with asset-based lineage and better observability
- Decision
- Dagster Cloud for serverless deployment—explicit dependency graphs and software-defined assets
ClickHouse over PostgreSQL
Why
- Context
- Analytical queries on large datasets were slow in row-based stores
- Decision
- Columnar ClickHouse Cloud for 10x query performance—sub-100ms dashboards instead of 5-10 minute waits
Architecture
The primary system boundaries, runtime pieces, and how the project was structured in production.
- MySQL DB → CDC Engine
- MongoDB → CDC Engine
- CDC Engine → Raw Tables
- Raw Tables → dbt Views
- dbt Views → Metabase
- Sling + DLT
Extract Layer
How
Sling pulls MySQL tables incrementally every 6 hours (only new/changed rows), DLT pulls MongoDB collections (full sync).
- Dagster Cloud
Orchestration
How
Manages job dependencies, schedules, and asset-based lineage—runs in serverless mode with proper dependency graphs.
- DBT Core
Transform
How
Creates denormalized views (orders_data, product_data) with business logic and data quality rules applied after raw loads.
- ClickHouse + Metabase
Warehouse + Consumption
How
Raw data lands in ClickHouse (tables prefixed: buyogo_mysql_*, dlt_new_mongo_*), business users query via Metabase dashboards.
Mermaid source
Paste into mermaid.live to edit the diagram.
flowchart LR
  subgraph Sources [Data Sources]
    MYS[(MySQL DB)]
    MGO[(MongoDB)]
  end
  subgraph Ingest [Sling & DLT]
    CDC[CDC Engine]
  end
  subgraph Warehouse [ClickHouse Cloud]
    RAW[(Raw Tables)]
    DBT[dbt Views]
  end
  subgraph BI [Analytics]
    DASH[Metabase]
  end
  MYS --> CDC
  MGO --> CDC
  CDC --> RAW
  RAW --> DBT
  DBT --> DASH
Pipeline
How changes moved from development through validation and deployment.
MySQL incremental every 6h via Sling, MongoDB full sync via DLT
Raw data lands in prefixed tables: buyogo_mysql_*, dlt_new_mongo_*
Creates orders_data and product_data views with business logic
Manages dependencies, retries, scheduling via GitHub Actions deployment
Branch-based: main→prod, staging→staging, test→testing environments
Dashboards for processed data with better visuals
Select a step for its detail
Incidents
Operational failures, rehearsals, or recovery moments that changed how the system was run.
- P2
DBT temp table conflicts in shared ClickHouse
Resolution
Added cleanup query to pipeline—DBT temp tables now cleaned between runs
Lesson: Shared ClickHouse schema needs explicit cleanup between runs; don't assume automatic cleanup
- P2
Memory spike during MongoDB initial batch extraction
Resolution
Configured DLT chunk streaming with bounded buffer size instead of in-memory collection
Lesson: Always stream large document collections in bounded batch chunks when extracting to ClickHouse